
Prerequisites
Make sure that your system satisfies the prerequisites given on the main course page. We will use Visual Studio Code, but not Nsight Systems, in this practical.
Start Visual Studio code and, if you plan to run code on a remote machine, connect to it.
Introduction (10 minutes)
The example code implements a simple feed-forward neural network to predict hourly trips of the Capital bike sharing scheme in Washington D.C. It implements both the forward and backward passes (there is no automatic differentiation!), an Adam optimizer, and the training and testing loop. The data (provided) gives the number of trips for each hour of 2019, aggregated over the entire city. Features include weather and sunlight.
The model can be described mathematically as follows. For each hour we predict the number of trips from features using a neural network with number of layers. The forward pass is given by:
where superscript denotes rectification and the final layer (which will actually be a scalar, so we also write ) forms the prediction (we reserve for the actual observation). The parameters are the weight matrices and bias vectors for .
We train the model by minimizing the mean of the squared error over all data points. The backward pass computes the gradient of this loss with respect to the parameters. Recall that, for a scalar function with vector argument, , given and , we have:
The loss function is such a scalar function. We can compute all necessary gradients by working backward, recursively applying the chain rule (the same order as for reverse-mode automatic differentiation):
where denotes the Heaviside step function:
Notice that we need to preserve the values of , and from the forward pass in order to perform these calculations. We can discard the , however, which simplifies the implementation somewhat. In practice we will use mini-batches of data by stacking multiple data points as columns of a matrix of and elements of a vector . The computations are analogous.
For more detail on reverse-mode automatic differentiation, which we have just unrolled above, see Matrix Gradients of Scalar Functions.
Orientation (10 minutes)
We will start by obtaining the source code from GitHub.
From within Visual Studio Code, connect to your GPU instance, open a new terminal, and enter:
git clone https://github.com/lawmurray/gpu-course.git
cd gpu-course
On the left Explorer pane in Visual Studio Code, open
the gpu-course directory to access the files.
The source code is split into the following files:
src/config.h- Contains global configuration options. We will experiment with these shortly.
src/init.handsrc/init.c- Contains routines for CUDA initialization.
src/data.handsrc/data.c- Contains routines for the data, including initialization, termination, and shuffling.
src/model.handsrc/model.c- Contains routines for the model, including initialization, termination, forward and backward passes.
src/optimizer.handsrc/optimizer.c- Contains routines for the Adam optimizer, including initialization, temination and gradient-based updates of parameters.
src/function.handsrc/function.cu- Contains kernels to execute on the GPU.
src/main.c- Contains the main program that reads in the data, initializes the model and optimizer, and runs the training and testing loop.
Not familiar with C?
C code is separated into header files and source files. The header files declare functions and the source files define them. Alternatively, we can think of the headers as providing the interface and the source files the implementation. Within any header or source file we can #include any number of header files to access additional functionality, analogous to importing packages in other languages.
By convention we use the following file extensions: -
*.h for header files, - *.c for source
files, - *.cu for source files that contain CUDA
language extensions.
The build is controlled by the Makefile, which
provides the commands to execute when calling make on
the terminal. These commands use the CUDA compiler nvcc
to compile function.cu, and your system compiler
(probably gcc) for the remaining *.c
files.
Not familiar with C?
Header files do not get compiled, only source files.
The data is provided in bikeshare.csv. The last
column is the standardized label, the other columns are all
features.
Building and running (10 minutes)
From within the gpu-course directory, build the
program with:
makethen run it with:
./mainIf either of these commands fails you may be missing some dependencies. If the code is running successfully, you will see one line per epoch, reporting test loss and elapsed time.
Throughout the following, whenever you are asked to build and run
the code again, just rerun those two commands: make to
build and ./main to run.
Simple tests (10 minutes)
Let’s verify some of the assertions in the opening lecture. The
file src/config.h defines macros
(#define NAME value) with various configuraiton options
that we can modify.
Open src/config.h for editing in Visual Studio
Code.
Kernels
For BLOCK_SIZE, try a few different power-of-two
values, e.g. 32, 64, 128, …, 1024. After each change, build and run
the program. How does performance vary? Choose a value that seems to
optimize performance and set it to this. The existing choice, or
something larger, is likely optimal.
When the block size is too small, we do not use the full capacity of the GPU, and so execution is slower. Setting the block size above 1024 will not work, as 1024 is the maximum size supported (this may vary by hardware and CUDA version).
The example code does not do much error checking and may appear
to run with BLOCK_SIZE greater than 1024. We will touch
on more robust practices in the closing lecture.
Streams
Run the code with:
CUDA_LAUNCH_BLOCKING=1 ./mainThis command sets the environment variable
CUDA_LAUNCH_BLOCKING to a value of 1. CUDA
recognizes this and makes all kernel launches blocking,
which is to say synchronous rather than
asynchronous with respect to the CPU. Each time the CPU
enqueues a kernel for the GPU, it will wait for the GPU to complete
the work before proceeding.
The execution time should increase as a result of running this way. This highlights the importance of streaming computation when working with GPUs.
Floating point precision
Set ENABLE_SINGLE to 0 to use double
precision instead of single precision. Build and run again to see
how the execution time increases. How much slower is double
precision? Once finished, restore ENABLE_SINGLE to
1.
Depending on your hardware, it could be anywhere from 2 to 64 times slower in double precision than single precision.
If you see a degradation in line with the ratio of single to double precision performance of your hardware, as measured in peak FLOPS, this might be interpreted as a good sign: at least the program performance is compute bound by instruction throughput rather memory bound by memory access latency.
Cleaning up
To finish up this section, make sure that the only change
remaining in src/config.h is your choice of
BLOCK_SIZE. Build one last time to make sure it is up
to date.
Using git diff will identify any unintentional
changes. If you simply want to reset back to the original sources,
use git checkout . from within the
gpu-course directory.
Exploration (20 minutes)
Take some time to browse through the code to better understand how it works.
The remaining material highlights some of the important points that you may discover during your exploration.
Building
The Makefile is worth a brief look. The CUDA
compiler is nvcc. It works mostly as a wrapper around
the system compiler (probably gcc), but
behind-the-scenes calls the CUDA toolchain to compile CUDA-specific
code.
Floating point literals
Throughout the code, notice that floating point literals are
written with the suffix f, e.g. 0.0f and
1.0f instead of 0.0 and 1.0.
Literals in C are typed: for floating point literals the
f suffix denotes type float, while the
absence of a suffix denotes type double.
In C, operands to arithmetic operations undergo numerical
promotion, e.g. - adding a float to a
float returns a float, - adding a
double to a double returns a
double, - adding a float to a
double or vice-versa returns a double.
In the final case, the operand of float type is
promoted to double type before the addition.
If we are sloppy with literals, we can inadvertently perform computations that we intend to be in single precision in double precision instead. On GPUs in particular this has significant performance implications.
Memory allocation
Not familiar with C?
C is not a managed language, so it is the programmer’s responsibility to allocate and free memory as required. In a managed language this is handled by the runtime when, for example, objects and arrays are created and eventually garbage collected.
Note the initialization and finalization idiom: the source files
src/data.c, src/model.c and
src/optimizer.c define the structs data_t,
model_t and optimizer_t, which are
initialized by the functions data_init(),
model_init() and optimizer_init(), and
finalized by the functions data_term(),
model_term() and optimizer_term(). The
former set of functions allocate memory for all variables in the
structs, while the latter set free it.
Not familiar with C?
A struct declares a compound type consisting of
several variables. These are like classes in other languages,
without support for member functions.
To allocate virtual memory accessible only by the CPU, we use the
standard C library functions malloc()
and free().
To allocate virtual memory that can be accessed by both the CPU and
GPU, we use the CUDA Runtime API functions cudaMallocManaged()
and cudaFree().
We have a number of different memory allocation alternatives
available:
| Allocate | Free | Description | Accessible by |
|---|---|---|---|
malloc() |
free() |
Virtual host memory | Host only |
cudaMalloc() |
cudaFree() |
Device memory | Device only |
cudaMallocAsync() |
cudaFreeAsync() |
Device memory | Device only, asynchronous |
cudaMallocHost() |
cudaFreeHost() |
Pinned host memory | Host and device |
cudaMallocManaged() |
cudaFree() |
Managed memory | Host and device on demand |
In the exercises above, ENABLE_PINNED had the effect
of converting all cudaMallocManaged() calls to
cudaMallocHost(), and all cudaFree() calls
to cudaFreeHost().
Kernels
The source file src/function.cu provides kernel
functions and, for each, an associated wrapper function. For example
rectification is implemented in the kernel
kernel_rectify(), which we call via the associated
wrapper function rectify(). This pattern makes calling
code that runs on GPU more convenient, as the wrapper function can
establish the execution configuration rather than the caller.
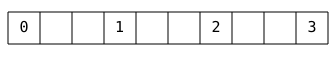
The code follows BLAS/LAPACK conventions on the representation of vectors and matrices. A vector is specified by providing:
- a base pointer (e.g.
x), and - an increment between elements (e.g.
incx), such that - the
ith element is given byx[i*incx].
Not familiar with C?
Arrays a zero-based, i.e. for array x the first
element is x[0] and the second x[1],
etc.
For example, the elements of a vector of length 4 with an increment of 3 appear in memory as:
If we wish to apply a transformation to all elements of a vector, we might write a loop:
for (int i = 0; i < nelements; ++i) {
  x[incx*i] = f(x[incx*i]);
}
We could instead parallelize it by writing a kernel:
__global__ kernel_f(int nelements, float* x, int incx) {
  int i = blockIdx.x*blockDim.x + threadIdx.x;
  if (i < nelements) {
    x[incx*i] = f(x[incx*i]);
  }
}
The __global__ keyword is a CUDA language extension
for specifying a kernel. Once launched, the kernel is executed
for each thread in a grid of blocks of threads (recall: the
execution configuration). To determine which particular thread an
execution pertains to, we use the built-in variables:
blockIdx.x, which gives the coordinate of the block within the grid,threadIdx.x, which gives the coordinate of the thread within the block,blockDim.x, which gives the size of each block.
Notice the guard if (i < nelements) { ... }. The
execution configuration may not evenly divide through the number of
elements, so we should ensure—with a conditional like this—that the
particular thread actually has any work to do.
We can launch the kernel on the GPU with:
dim3 block(256); // ❶
dim3 grid((nelements + block.x - 1)/block.x); // ❷
kernel_f<<<grid,block>>>(x, incx); // ❸
Recall from the opening lecture that we launch a kernel using an
execution configuration that specifies the size of a grid
of blocks of threads. Line ❶ configures the block size to 256
threads (setting the block variable). Line ❷ configures
the grid size to a sufficient number of blocks for one thread per
element (setting the grid variable). Line ❸ launches
the kernel, passing grid and block in
triple angle brackets after the name of the kernel—this is a CUDA
language extension for specifying execution configurations.
Not familiar with C?
The code
(nelements + block.x - 1)/block.xabove is a convenient way to write the > integer division “nelementsdivided byblock.x, rounding up”.
A matrix is stored column-major, and is specified by providing:
- a base pointer (e.g.
A), and - a lead between columns (e.g.
ldA), such that - the
(i,j)th element is given byA[i + ldA*j].
For example, the elements of a 3 by 4 matrix with a lead of 4 and column-major layout appear in memory as:

If we wish to apply a transformation to all elements of a matrix, we might write a loop:
for (int j = 0; j < nrows; ++j) {
  for (int i = 0; i < ncols; ++i) {
    A[i + ldA*j] = ...;
  }
}
We could instead parallelize it by writing a kernel:
__global__ transform_f(int nrows, int ncols, float* A, int ldA) {
  int i = blockIdx.x*blockDim.x + threadIdx.x;
  int j = blockIdx.y*blockDim.y + threadIdx.y;
  if (i < nrows && j < ncols) {
    A[i + ldA*j] = f(A[i + ldA*j]);
  }
}
and launch it with:
dim3 block(256, 1);
dim3 grid((nrows + block.x - 1)/block.x, ncols);
transform_f<<<grid,block>>>(nrows, ncols, A, ldA);
Note the similar conventions to the vector case, but we are now
working with a two-dimensional execution configuration, and so use
the additional y members of blockIdx,
threadIdx and blockDim. A further
z member is available to support three-dimensional
execution configurations.
Model forward and backward passes
With respect to the model, the most important functions are
model_forward() and model_backward() in
src/model.c, which implement the forward and backward
passes, respectively. The forward pass takes a minibatch of features
and outputs a prediction. The backward pass takes the prediction and
computes the gradient of the loss with respect to the parameters.
The implementation aligns with the mathematical description
above.
Summary
In this practical we have learned how to build and run a CUDA program. We have done some simple experiments on floating point precision and execution configurations to better understand performance tradeoffs. Finally, we have had a deep dive into the code to see how memory for the GPU is allocated and freed, and how kernels are specified and launched using specific CUDA language extensions.
Possible extensions
- Alternative activation function
-
The model is implemented using rectification. We could replace this
with an alternative activation function, such as a sigmoid, by
implementing functions analogous to
rectify()andrectify_grad().