Foundations of GPU Computing
Lawrence Murray
Course outline
Course materials are at https://indii.org/gpu-course/
- Introductory Lecture
- No code here, just concepts to start. GPU hardware, memory hierarchies, kernel configurations, streaming computation, floating point precision and performance.
- Practical Exercises 1
- Hands-on with example code. Building and running CUDA programs, single versus double precision performance, vector and matrix kernels, memory management.
- Practical Exercises 2
- Profiling code, identifying issues, assessing headroom, improving concurrency.
- Closing Lecture
- More streaming computation, and advanced kernel programming.
Foundations of GPU Computing: Introductory Lecture
Lawrence Murray
Outline
- Introduction to GPU hardware.
- How a CPU and GPU work together.
- Key concepts of GPU programming: kernels, streams, memory.
- Floating point precision and performance.
No code here, just concepts.
What is a GPU?
- CPU (Central Processing Unit)
- A processor for general compute loads: desktops, servers, databases, scientific computing.
- GPU (Graphics Processing Unit)
- A processor for specific compute loads: initially graphics, eventually scientific computing too, recently deep learning especially.
What is a GPU?
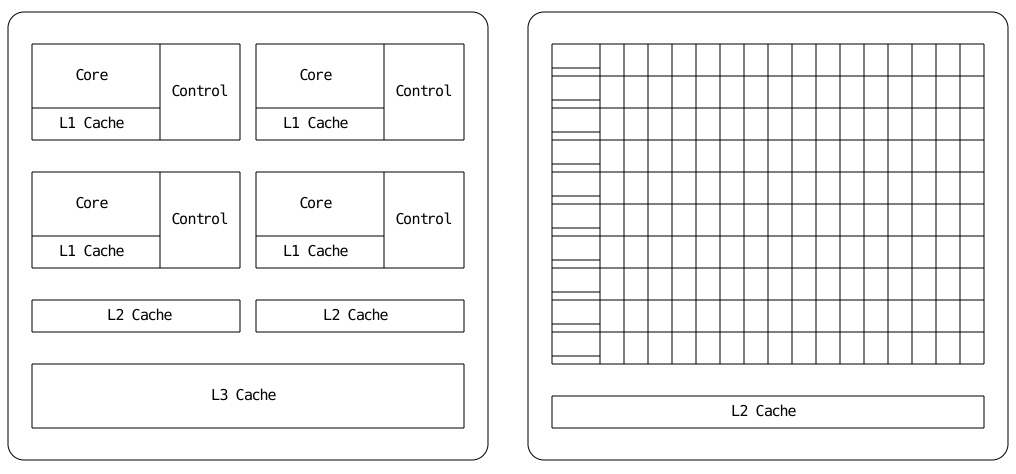
CPUs and GPUs represent different design tradeoffs for these different use cases.
What is a GPU?
| CPU: Intel Core i9-13900K | GPU: GeForce RTX 4090 | GPU: H100 | |
|---|---|---|---|
| Cores or SM count | 24 | 128 | 114 |
| Clock rate (GHz) | 5.5 | 2.5 | 1.7 |
| L1 Cache (KB per core) | 80 | 128 | 256 |
| L2 Cache (MB total) | 32 | 72 | 50 |
| L3 Cache (MB total) | 36 | 0 | 0 |
| Single precision (TFlops) | ? | 82.58 | 51.22 |
| Double precision (TFlops) | ? | 1.29 | 25.61 |
What is a GPU?
- The CPU:
- has a faster clock speed,
- tries to hide memory latency by using cache on the principle of spatiotemporal locality (once a memory address is accessed, it is likely that the same or nearby addresses will be accessed again soon).
- The GPU:
- has a slower clock speed,
- uses cache too, but mostly tries to hide memory latency by using oversubscription with a large number of threads: while one group of threads is waiting on memory operations, another can be executing.
When might we consider using a GPU?
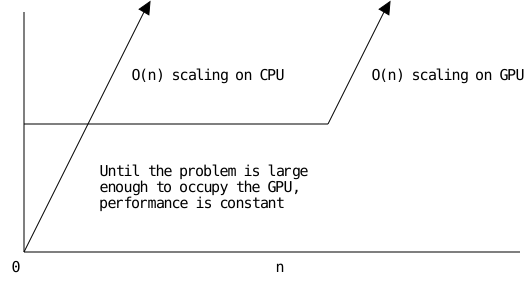
Where our computation has critical components that have large scale data parallelism.
- On modern GPUs, way data parallelism is ideal, in that it can occupy the whole device, e.g. multiplying two matrices of size at least .
- Failing that, we may be able to run multiple tasks concurrently that in aggregate have enough data parallelism to occupy the device.
Example use cases
- Core computations:
- Large matrix multiplication
- Large matrix factorization
- Large differential equation solvers
- Convolutions
- Large transformations and reductions
- Applications:
- Image processing (4)
- Numerical weather prediction and other physical simulation (3)
- Deep learning (1, & 4 for CNNs)
- Gaussian processes (2, Cholesky factorization in particular)
- Sequential Monte Carlo (5)
Misconceptions (or: more nuance required)
CPUs do serial computation, GPUs do parallel computation- Modern CPUs and GPUs are both highly parallel devices. It is true, however, that for straight serial computation a CPU is faster (recall: it has a faster clock rate).
CPUs do task parallelism, GPUs do data parallelism- Both do both, although there needs to be at least some data parallelism for the use of a GPU to be worthwhile. Arguably, programming task parallelism is easier on CPU than GPU (e.g. OpenMP, C++ standard library, pthreads and other libraries are easier to use than concurrent kernel execution), and programming data parallelism is easier on GPU than CPU (e.g. scalar programming within kernels is easier than vector programming with masking).
GPUs are 100x faster than CPUs- For the right computation, expect a 5-20x speedup. Anything more suggests that the CPU baseline needs work.
How do the CPU and GPU work together?
- By way of nomenclature, we often refer to the CPU as the host and the GPU as the device.
- The main program runs on the CPU (host) but it offloads particular tasks to the GPU (device).
Streaming
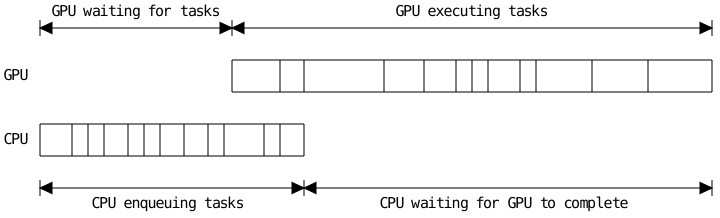
- The CPU executes the main program, which enqueues kernels into a stream.
- The GPU executes the kernels in the stream in the order enqueued.
- The CPU must synchronize with the stream (wait until the GPU has finished execution) to obtain the results.
Kernels
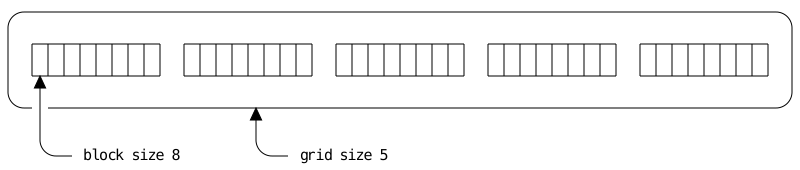
When the GPU executes a kernel, it does so with many threads.
Threads are organized into a two-level hierarchy by an execution configuration:
- First into equal-sized blocks, each of which is an array of threads.
- Second into a grid, which is an array of thread blocks.
These arrays can be one, two, or three dimensional.
Vector kernels
For example, a one-dimensional execution configuration, which might be used to distribute work over the elements of a vector:
Matrix kernels
A two-dimensional execution configuration, which might be used to distribute work over the elements of a matrix:
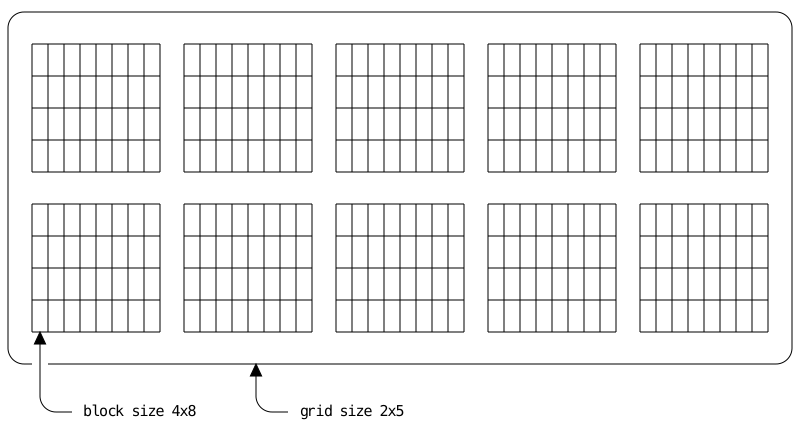
For good performance, the total block size should be at least 256, and has a hard maximum of 1024.
Memory
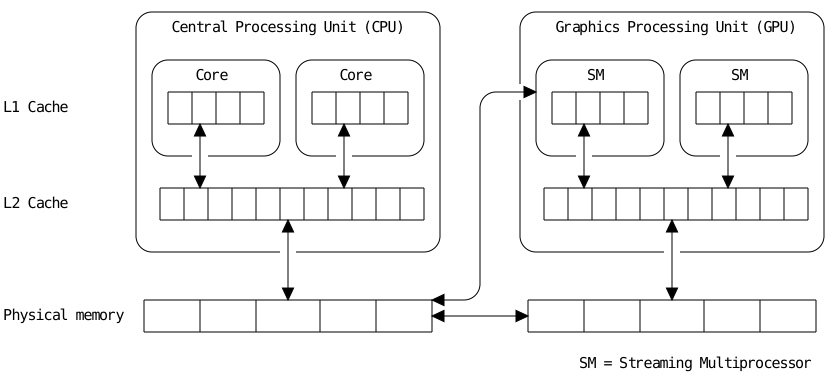
The CPU and GPU are physically separate and connect via the PCIe bus. The CPU uses main memory (also called host memory), the GPU uses its own device memory.
Memory
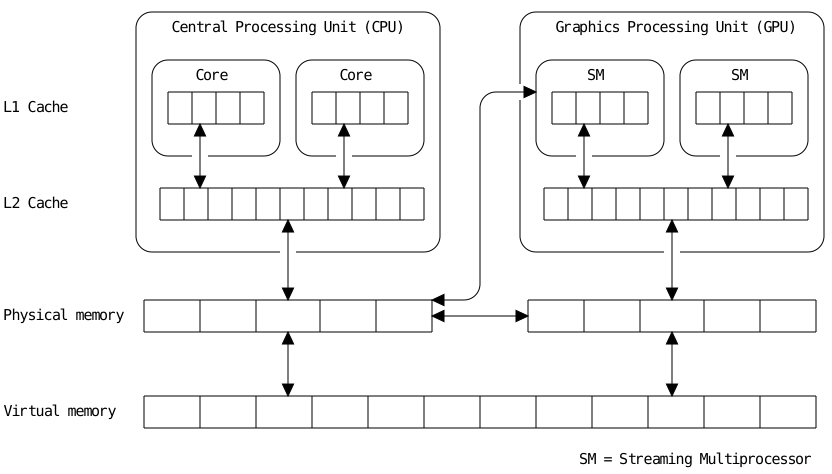
More recent architectures unify the separate memory via virtual memory. Pages swap on-demand between main and device memory via the virtual memory system.
Memory
- Virtual memory to physical memory
- Operates on pages. The page size varies between platforms from 4 KB to several MB depending. Whole pages are swapped between physical memory and disk, even if only partly used.
- Physical memory to cache
- Operates on cache lines. The cache line size varies between architectures, but is typically 64 bytes on CPU and 128 bytes on GPU. Whole cache lines are read or written, even if only partly used.
Being aware of this will help you write more efficient code. We can minimize the number of cache line reads by ensuring that all threads in the same block read from the same cache lines.
Some (older?) materials refer to coalesced memory access for high performance on GPU. This is a stricter condition where adjacent threads should access adjacent addresses in memory, not just the same cache line. It is no longer necessary, except when accessing pinned host memory from the GPU, which is not cached.
Floating point precision
Extended precision (80 bits, alternatively called long double)

Double precision (64 bits)

Single precision (32 bits)
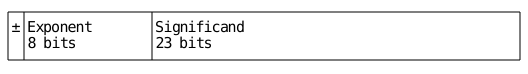
Half precision (16 bits)
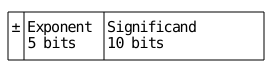
Floating point precision
- For scalar operations:
- CPUs use extended precision for intermediate results held in registers, and these are rounded to double, single, or half precision when written to memory.
- GPUs use only double, single, or half precision throughout.
- For vector operations:
- CPUs use only double, single, or half precision throughout.
- GPUs use only double, single, or half precision throughout.
GPUs do not use extended precision at all!
Floating point performance
GPUs have much faster performance in half (16 bit) and single (32 bit) than double (64 bit) precision.
The gains come from two sources: 1. The hardware has greater throughput in half and single precision than double precision, ranging from a ratio of 2:1 for data center products such as the H100, to 64:1 for consumer products such as the GeForce RTX 4090. The gap has widened over the years. 2. Lower precision requires less memory overall, meaning smaller transfers between host and device, memory and cache, and that cache stretches further on a per-element basis.
How do we program a GPU?
- CUDA
- For Nvidia GPUs. Also provides libraries such as CUBLAS, CUSOLVER, CURAND, CUDNN.
- ROCm
- For AMD GPUs, and within it HIP that targets both Nvidia and AMD GPUs.
- SYCL
- Open standard portable across Nvidia, AMD, and Intel GPUs, although may require components of the above for Nvidia and AMD hardware. Implementations include Intel’s oneAPI, which includes the Intel Math Kernel Library for linear algebra and the Data Parallel C++ library for standard transformation and reduction primitives. Builds on OpenCL, and probably favored for programmability nowadays.
- OpenMP
- Has support for offloading to GPU since version 4.0, allowing parallelization on GPU using similar directives as for CPU. However, library support may still require one of the above.
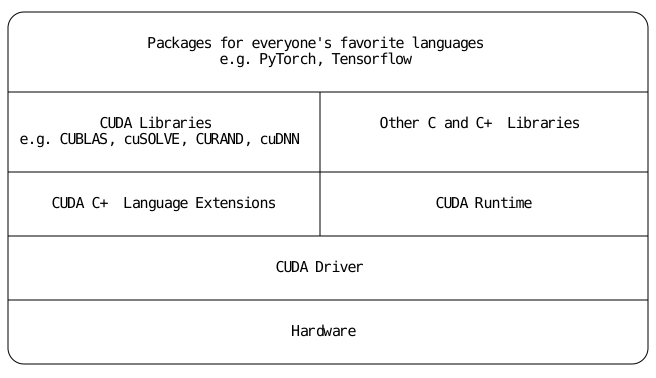
CUDA Stack
We use CUDA for the practical exercises in this course.
- On the upside, CUDA is the most established option for general-purpose GPU computing, with the most extensive libraries available.
- On the downside, it is not open source and not portable across hardware vendors.
Summary
CPUs and GPUs represent different tradeoffs in hardware design for different use cases.
- Memory
- The CPU and GPU have separate memory and cache hierarchies. Virtual memory unifies the separate memory.
- Streams
- The CPU enqueues kernels into a stream, the GPU executes them asynchronously.
- Kernels
- Kernels are launched onto the GPU with a one, two, or three-dimensional execution configuration, defining a grid of blocks of threads.